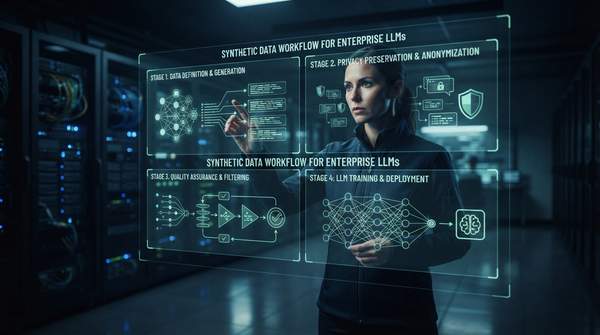
Yes—for most enterprises hitting a wall on data access, privacy rules, or annotation cost, synthetic data is a viable and increasingly standard way to train and fine-tune large language models. It is not a shortcut around quality control, and it will not guarantee a particular performance uplift, because results are highly use-case dependent. What it does offer is a structured, scalable path from a defined data need to a specialized model, built around four stages: preparing source inputs, generating synthetic examples, validating quality and bias, and fine-tuning the model. Below we walk through why enterprises adopt this approach, how the workflow runs end to end, which generation methods fit which needs, and how to judge whether it fits yours.
The Enterprise Data Dilemma: Why Synthetic Data for LLMs?
Three pressures push enterprises toward synthetic data. First, scarcity and cost: as Muhammad Arham writes in a CircleCI tutorial, creating and labeling conversational data manually is "time-consuming, laborous, and often expensive," making automated generation attractive for supervised training. Second, privacy: Curiosity Software's Mantas Dvareckas argues that simulating production-like data without real identities enforces privacy "from the outset, removing the need for masking or obfuscation"—what he calls compliance by design. Third, control: a 2025 arXiv survey of LLM-based data generation notes that synthetic data can be tailored to specific needs—covering edge cases, generating counterfactuals to debias a model, or targeting low-resource languages and rarely seen contexts.
The same survey points to a forward-looking motivation: researchers predict that real text data available for training may plateau in coming decades, making synthetic data potentially crucial for sustaining model improvements. For an enterprise today, the more concrete framing is this: when your domain is narrow, your real data is sensitive or regulated, and your annotation budget is finite, generating fit-for-purpose text data can be the difference between a generic model and a useful one.
Conceptual Workflow for Enterprise Synthetic Data Generation
Use this four-stage framework to plan a synthetic data initiative. Each stage has a distinct purpose, a set of key activities, and a concrete output that feeds the next stage—and the sequence matters, because the effectiveness of synthetic data is contingent on careful preparation, generation, validation, and integration, not on generation alone.
| Stage | Purpose | Key Activities | Output |
|---|---|---|---|
| Source Data Preparation | Define what "good" data looks like for your task and gather seed material. | Specify target attributes, formats, and coverage; select example data or seed documents to anchor generation. | A clear data specification plus seed examples or instructions. |
| Synthetic Data Generation | Produce new text that mimics the desired characteristics. | Configure generation models and inference parameters; apply prompting, retrieval, or iterative methods; generate at scale. | A raw synthetic dataset in a usable format (for example, question-answer pairs saved for downstream training). |
| Data Quality Validation | Confirm the data is fit for training and not harmful. | Filter outputs, run automated quality metrics, check diversity and relevance, detect bias and privacy leakage. | A validated, curated dataset approved for training use. |
| Model Training & Fine-Tuning | Improve model performance on your specific tasks. | Instruction-tune or fine-tune a pre-trained model; track downstream performance impact. | A specialized model and a baseline for measuring training effectiveness. |
The critical caveat, visible in the table's logic: the quality of synthetic data relies heavily on the clarity and relevance of the initial inputs and definitions. A vague specification in stage one produces a noisy dataset in stage two and unreliable results in stage four, no matter how sophisticated your generation method is.
Key Synthetic Data Generation Methods for Enterprise Needs
Generation techniques span a spectrum of complexity and control, and the optimal method depends on the desired data characteristics, available resources, and the specific fine-tuning task. The arXiv survey categorizes the major approaches as prompt-based augmentation, retrieval-augmented generation, self-instruct methods, and reinforcement learning with feedback—distinguishing strategies like zero-shot versus few-shot prompting, knowledge integration, and iterative refinement.
Simple prompting is the low-cost entry point: you ask a capable model to produce examples matching your specification. Pipeline-based approaches add structure. Microsoft's Evol-Instruct, cited by Red Hat's Cedric Clyburn and Carol Chen, is one automated pipeline example; their article also describes InstructLab, developed by Red Hat with IBM Research, which translates traditional data sources into seed examples for generation, implements rigorous filtering, and uses multiphase tuning—maintaining training stability and a replay buffer to help prevent catastrophic forgetting. Notably, InstructLab structures a taxonomy of data so subject matter experts can contribute without deep data science expertise, a model well suited to enterprises where domain knowledge lives outside the ML team.
Automation extends beyond generation itself. Arham's CircleCI walkthrough demonstrates the full loop: scraping current online content, filtering irrelevant or short paragraphs, generating question-answer pairs on the fly, and running the whole process on a daily schedule via a CI/CD pipeline so the dataset refreshes continuously. For enterprises whose source material changes—support articles, product docs, regulatory updates—that continuous pattern keeps training data aligned with reality.
Ensuring Quality and Mitigating Bias in Synthetic Datasets
Validation is where synthetic data initiatives succeed or fail. RunPod's guidance on AI model development recommends continuous quality assessment through automated metrics and downstream performance evaluation, alongside bias detection systems that identify unwanted biases while maintaining diversity and training utility, and performance impact analysis to track how synthetic data affects model behavior and business outcomes. In other words, quality control is not a one-time gate before training; it is a monitoring discipline that continues as you regenerate and scale datasets.
Two risks deserve particular attention. First, bias: because generation inherits patterns from both the seed data and the generating model, counterfactual generation and explicit diversity checks—capabilities the arXiv survey highlights as advantages of controllability—need to be exercised deliberately, not assumed. Second, privacy leakage: recent research catalogued in a curated synthetic-data repository includes a 2026 statistical auditing framework, "Phantoms and Disclosures," which distinguishes true from "phantom" disclosures in LLM-generated synthetic data and yields tighter empirical privacy-leakage bounds. The takeaway for enterprises: synthetic does not automatically mean private, so audit for memorized or traceable content before treating a dataset as compliant.
Integrating Synthetic Data for Enhanced LLM Performance
In the final stage, validated synthetic data feeds instruction-tuning or fine-tuning of a pre-trained model. This is the typical enterprise pattern: synthetic data augments or replaces the manual annotation that supervised fine-tuning would otherwise require, and NVIDIA's synthetic data guidance for agentic AI points to the same integration point—designing high-fidelity synthetic datasets for large-scale model training in domains like tax form validation, legal documents, and mortgage approvals, configured through model selection and tuned inference parameters to get the right output quality and style.
On the question of how much synthetic data helps, the honest answer is: it depends, and this article does not offer a definitive benchmark. The arXiv survey highlights empirical findings of 3–26% improvements with synthetic augmentation in low-data regimes, and notes that prompt design and data curation strongly affect quality. Recent research in the curated repository also distinguishes fixed-source synthesis from source expansion in scaling, suggesting that per-question response budgets are a bounded axis while expanding seed questions wins at large budgets. The practical reading: gains are real but use-case dependent, and expanding diverse seed material matters more than simply generating more responses from the same seeds.
Deciding on Synthetic Data for Your Enterprise LLM Strategy
Enterprise AI leaders should evaluate synthetic data as a strategic solution for LLM training when facing challenges such as data scarcity, privacy concerns, or the need for highly specialized and controlled datasets. The decision framework is straightforward: if manual annotation is slow and expensive, if real data is sensitive or hard to obtain, or if you need deliberate coverage of edge cases and underrepresented contexts, the four-stage workflow above is a viable path. If you already have abundant, clean, compliant, well-labeled data, the marginal value is smaller.
Scope matters too. This is a conceptual guide for text-based LLM training—not a coding tutorial, a review of specific generation platforms, or an approach suited to computer vision and other AI domains. Treat the workflow as a planning template your data team adapts to its own stack.
Successful implementation will be indicated by a reduction in manual data annotation efforts, improved model performance on specific tasks, and enhanced compliance with data privacy regulations. Set those three as your measurable indicators before you start: track annotation hours saved per training cycle, benchmark the fine-tuned model against your current baseline on the target task, and document privacy audit results for each synthetic dataset. If a pilot cannot move those numbers, synthetic data is not solving your problem—and if it can, you now know the four stages required to scale it.
Sources
- Real-time synthetic data generation for LLM training with CircleCI workflows - CircleCI
- How synthetic data can make your LLMs more accurate — Curiositysoftware
- Synthetic Data Generation Using Large Language Models: Advances in Text and Code — ARXIV
- Synthetic data: A secret ingredient for better language models — REDHAT
- Synthetic Data Generation for AI Models — Runpod
- GitHub - ahmad-alismail/LLM_based_Synthetic_Data_Generation: A curated and continuously updated collection of papers, tools,…
- Use Case: Synthetic Data Generation for Agentic AI — NVIDIA